纯文本 dsh 模型的识图插件:粘贴图片自动由你配置的多模态模型转成文字——透明孪生路由、模型可自主调用识图工具、无内置密钥与中转。
Vision for text-only dsh models: paste an image and a configured multimodal model transcribes it to text automatically — transparent twin routing, an agent-callable read-image tool, no built-in keys or relay.
安装
dsh plugin --profile web add github:Junkrat9527/dsh-autovisionGitHub 源码安装:首次需按提示配置 allowBuilds 构建授权后重试
安装与环境配置指引、插件开发教程见 DSH 中文社区文档 ↗
安装即在你的机器上以你的权限运行第三方代码——它可读写文件、使用凭据、访问网络,DSH 的工具审批不会为插件代码加沙箱。「检测到 manifest」仅代表发现 dsh.bundle / dsh.plugin 清单,不构成兼容性或安全审查;安装前请审阅源码,不熟悉的插件先在不含密钥的环境试用。
README
Vision for text-only models inside DeepSeek Harness — paste an image, and a configured multimodal model transcribes it to text automatically. No model switching, no built-in keys, no relay.
dsh-autovision gives text-only models (DeepSeek, GLM, …) real image support in the DeepSeek Harness web UI. It registers a transparent twin provider for every pure-text model, routes image-bearing requests to a multimodal model you configure yourself, and feeds the transcription back as text — so the text model "sees" the image without you switching models or touching the request.
⭐ If this plugin saves you time, please star the repo — it helps other dsh users find it.
Why
DeepSeek Harness only lets a model receive images when that model declares image input (inputModalities). Pure-text models (e.g. deepseek-*, glm-*) reject image messages — pasting a screenshot into a session either fails silently or errors out.
Existing workarounds made you switch models, use a third-party relay, or hardcode a key. dsh-autovision keeps your setup: the plugin never ships a key, never proxies through a relay, and never touches your model config. It simply borrows the multimodal model you already configured in dsh settings to transcribe images to text.
Features
- Zero-friction, transparent — every pure-text model gets a
<provider>-autovisiontwin registered at runtime.agent/requestauto-redirects each request to the twin, so you never switch models and never editsettings.yaml. - Paste → text, automatically — attach an image in the composer; it is transcribed by your configured vision model and injected into the text model's context. The original image stays visible in the UI (thumbnail + message), and the durable log keeps the original.
- Clean model selector — the twin's
listModelsreturns[], so the model picker shows only your real models. No noise. - Agent-callable
autovision_read_imagetool — the model can actively read an image file during a run, with its own per-task prompt (e.g. "transcribe every word", "describe the UI state"). - No built-in credentials — the recognition engine is whatever multimodal model you configure as the default vision model in the plugin settings (e.g.
opencode-go,minimax-m3). No API key, no relay URL, nothing hardcoded. - Survives
dsh upgrade— pure plugin implementation, zero patches to dsh core, zero config rewrites.
Install
Requires dsh web ≥ 0.1.0-rc.6.
dsh plugin --profile web add @iroam2375/dsh-autovision
The npm package is published as
@iroam2375/dsh-autovision(the bare namedsh-autovisionis unavailable on npm — too similar to the existingdsh-auto-vision). The plugin itself is still addressed by its bundle iddsh-autovision.
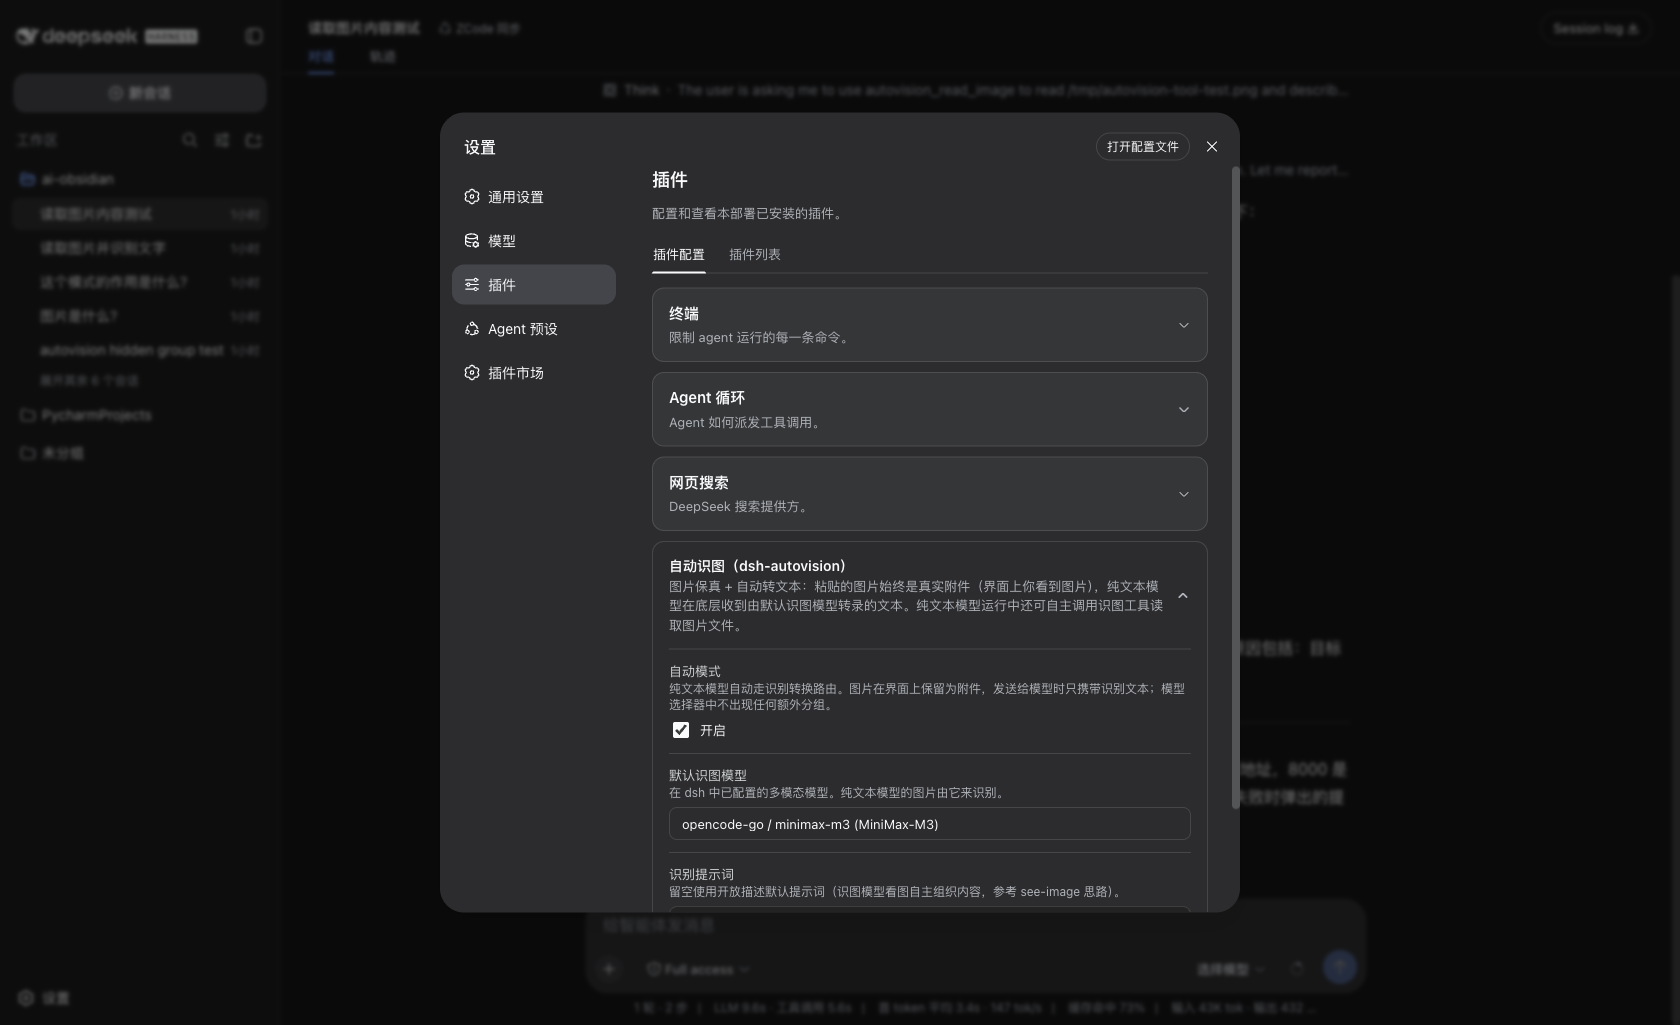
Restart dsh web, open 设置 → 插件 (plugin settings) → Autovision, and pick a default vision model (any multimodal model available in your LLM providers, e.g. minimax-m3 / opencode-go). That model does all the transcribing; nothing else is configured.
If you develop locally, the standard bundle wiring is used: add
"dsh-autovision"todsh.profile.bundlesin your profile'spackage.json. Do not also manuallyinsertit intocordis.patch.yml— that producesduplicate loader entry id: autovisionat boot.
Usage
- Paste an image into any session and send — the text model receives a faithful text transcription instead of the raw image.
- Ask the model to read a file — the model may call
autovision_read_imagewith a file path (and its own instruction) and act on the result.
Configuration
| Setting | Meaning |
|---|---|
defaultVisionModel |
Multimodal model used for transcription (from your LLM providers). No vision model → transcription degrades to a fixed placeholder instead of crashing. |
prompt |
Optional custom instruction for the vision model. Empty → an open-ended description prompt (text, colors, shapes, UI elements, layout, state). |
targetProviders |
Optional whitelist of providers to wrap (default: all). |
How it works
- For each pure-text model, the plugin registers a twin adapter (
<provider>-autovision) that declaresinputModalities: ['text', 'image']. agent/request(prepended) redirects each request to the twin; the twin'sstream()walks every image block in the wire messages (including tool-result nesting), transcribes each via the configured vision model (LRU-cached), and forwards text upstream.read_imagetool calls pass because the twin declares image input.- A runtime wrapper on
ctx.llm.resolveModelInfolets you manually switch to any wrapped text model mid-session without rejection — the request still routes through the twin.
Known limits
- A brand-new session whose very first message already contains an image is silently skipped; send one text message first and everything after works.
- Images up to 5 MB (attachment-local default).
- Transcription latency is the vision model's latency (e.g. 6–9 s for
minimax-m3), mitigated by an LRU cache. - The settings page may show one bare provider row (
opencode-go-autovision) with no address — cosmetic only, does not affect function.
Roadmap
- npm publishing (coming).
License
原始 README: https://github.com/Junkrat9527/dsh-autovision/blob/main/README.md ↗
同类插件
查看全部 →
modlens
为纯文本模型架起视觉桥梁:粘贴图片,输出结构化 JSON 证据(OCR、版面、语义)。

dsh-vision-toolkit
让纯文本模型更好地做视觉任务:带意图的图片问答、长截图 OCR、UI 还原等。

dsh-vision-router
为纯文本 Agent 提供视觉能力:内置免 Key 视觉链 + 像素级视觉工具(看图问答、定位、裁剪、像素对比、取色、OCR、矢量化、抠图、截图);粘贴图片即可用。

dsh-vision-complete
给 DeepSeek 补上「眼睛和耳朵」的多模态视觉插件:看图 / OCR / 物体检测 / 视频理解 / 语音转写 / 截图直读,一键安装(DSH 插件)。

dsh-media-skills
面向纯文本模型的免费视觉桥与生图:粘贴读图、GLM-4V-Flash 与 Gemini 引擎故障转移、modlens 同款结构化证据输出,并自动播种免费视觉模型路由。

dsh-vision-opencode
给纯文本主模型加可配置识图模型:vision_read_image 工具、输入框识图模型选择器,以及纯文本路由的图片自动转文字。