dsh-voice
by haoku123
Web UI 全双工语音对话:输入框麦克风(RMS 端点检测)配合浏览器本地 whisper 转写,回复按句流式朗读,开口说话即打断播放与正在运行的回合(真 barge-in),无需 API key。
Full-duplex voice mode for the Web UI: a composer mic (RMS endpoint detection) transcribes speech with whisper running locally in the browser, assistant replies stream back as spoken audio sentence-by-sentence, and speaking interrupts playback and the running turn (true barge-in). No API key.
安装
dsh plugin --profile web add github:haoku123/dsh-voiceGitHub 源码安装:首次需按提示配置 allowBuilds 构建授权后重试
安装与环境配置指引、插件开发教程见 DSH 中文社区文档 ↗
安装即在你的机器上以你的权限运行第三方代码——它可读写文件、使用凭据、访问网络,DSH 的工具审批不会为插件代码加沙箱。「检测到 manifest」仅代表发现 dsh.bundle / dsh.plugin 清单,不构成兼容性或安全审查;安装前请审阅源码,不熟悉的插件先在不含密钥的环境试用。
预览截图
README
Full-duplex voice mode for DeepSeek Harness: streamed ASR → LLM → TTS with barge-in.
Status
v0.7.0 — press-to-talk with a live caption.
Speak into the composer mic: the assistant silences itself (playback stops, host synthesis queue drops), the running turn is cancelled (the stop-button route), and your speech is transcribed by the host (SenseVoice, CN-native simplified-Chinese ASR with punctuation + ITN) and submitted. The reply streams back as spoken audio with live captions.
Three ways to dictate:
| gesture | behaviour |
|---|---|
| tap the mic | continuous dictation; the VAD segments on trailing silence |
| hold the send key (or the mic) | records until release, slide up to discard |
hold Ctrl (configurable asr.hotkey) |
same, without leaving the keyboard; Esc discards |
While a hold is open the overlay shows a live caption — the interim transcript of what has been said so far — and keeps a spinner up after release until the authoritative transcript lands.
Known limitation: barge-in detection is triggered by the mic's leading
speech edge, which relies on browser-level echo cancellation
(getUserMedia({ echoCancellation: true })). Loud TTS playback may leak
into the mic on some platforms; there is no JS-level AEC.
Demo
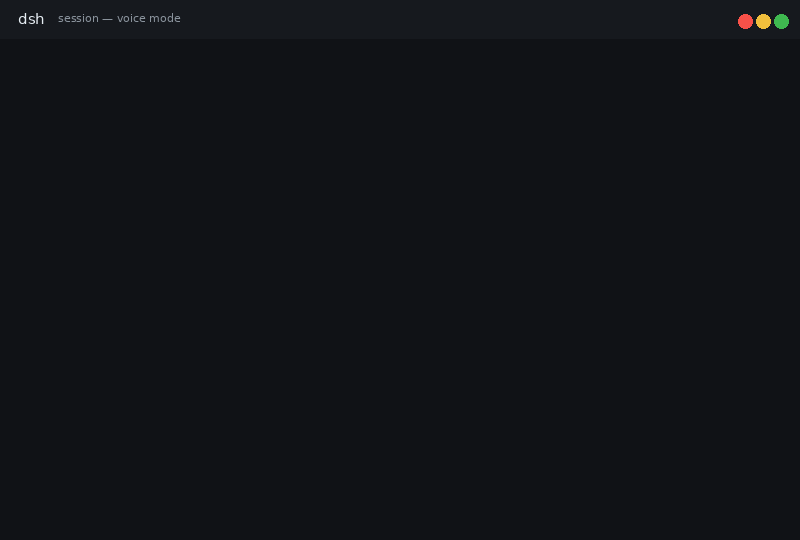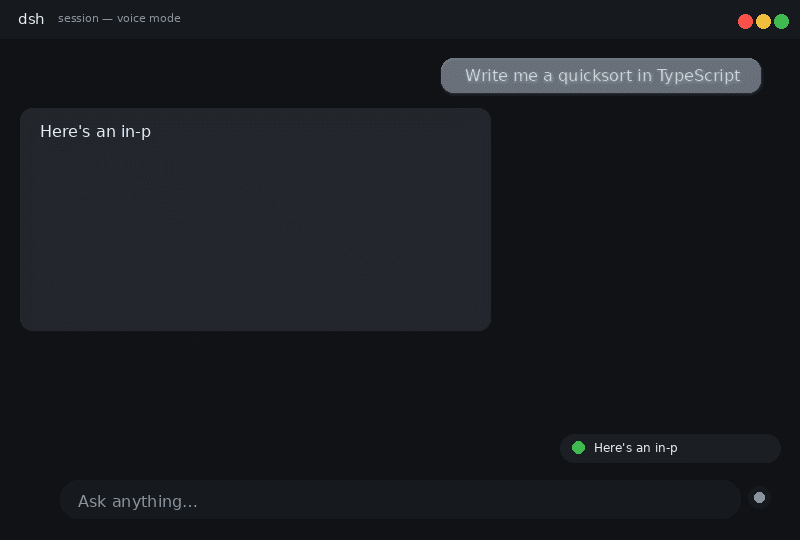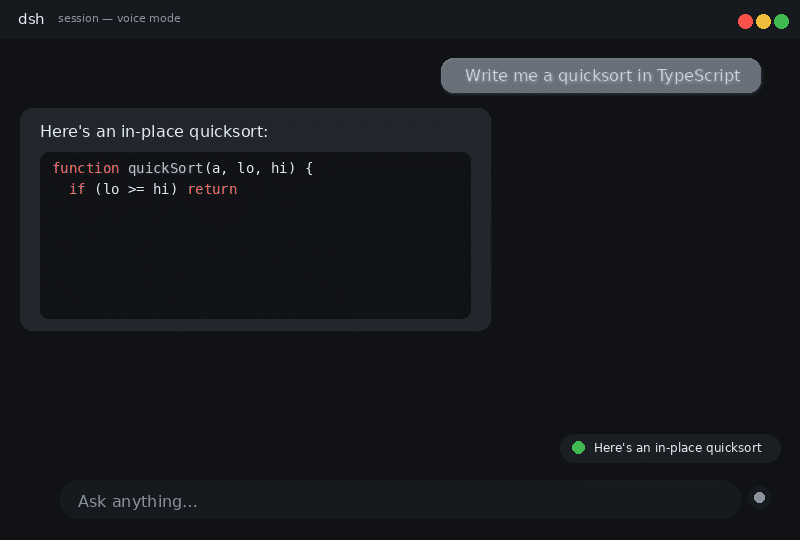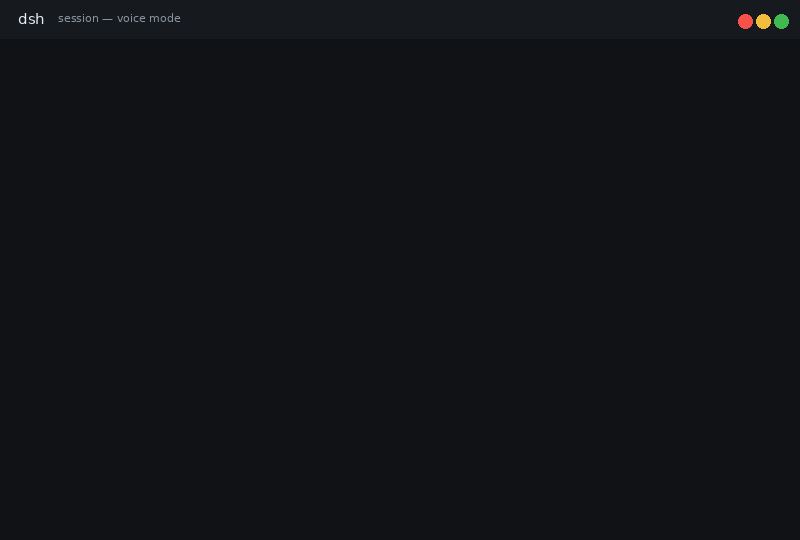
The loop: hold the composer's send key (its arrow is covered by a mic glyph),
watch the live caption fill in while you speak, release into a spinner until
the final transcript lands, then the reply streams back as spoken audio
sentence-by-sentence — until the user's voice interrupts playback and stops
the running turn mid-line (true barge-in). Ctrl does the same without
leaving the keyboard.
How it works
input:  mic ──RMS endpoint detection──▶ POST /asr (raw f32 PCM)
                                           │ text (SenseVoice)
                                           ▼
        composer draft ──submit──▶ model stream ──llm/stream tap──▶ SentenceSegmenter
                                                                     │
        browser ◀── SSE /dsh-voice-api/stream ── TtsQueue (msedge-tts) ◀──┘
                  (base64 MP3 frames + caption text)

barge-in: speech edge ──▶ engine.skip() + POST /cancel (epoch bump)
                         + session.cancel() when a turn is running
- The
llm/streamtap is lossless: every chunk is yielded unchanged, the segmenter only observes. The model stream is never blocked by synthesis. - ASR runs host-side with sherpa-onnx (Apache-2.0) running SenseVoice — the CN-native speech model that outperforms whisper on Chinese: native simplified output, punctuation, inverse text normalization (ITN) and 50+ language auto-detection. The browser only records and posts raw little-endian f32 PCM.
- Model files stream through a cache-through proxy at
/dsh-voice-api/hfand are mirrored to disk (~/.cache/dsh-voice/models/, configurable viacacheDir), so every browser/recognizer load after the first is served from local disk. Downloads resume from partial.partfiles when interrupted. Usenpm run prefetchto warm the cache once. - RMS endpoint detection: 16kHz getUserMedia, 2s trailing-silence cutoff, max 30s segment, pre/post padding. Zero dependencies.
- Press-to-talk bypasses the VAD entirely. Holding the key is already the intent, so every buffer between press and release is kept — gating on loudness there only drops quiet speech, which is indistinguishable from a broken button. Only captures below 250ms are discarded (mis-taps).
- Live caption: while a hold is open the engine re-decodes the buffer every ~900ms and shows the interim text. SenseVoice is not a streaming model, so this is only requested while the overlay is actually on screen, and stops past 12s of audio. Interims are strictly previews: they never reach the composer draft, and an interim that lands after the release is dropped (epoch check) so it can never overwrite the final transcript.
- Barge-in is three-layered: local playback queue cleared, host
TtsQueueepoch bumped (queued AND in-flight synthesis dropped), and the running turn cancelled whensession.runningis true. An aborted turn never flushes its trailing half-sentence — exactly what the user interrupted. modelHostaccepts any HF-compatible mirror (e.g.https://hf-mirror.comfor CN networks).
API
| Route | Purpose |
|---|---|
GET /dsh-voice-api/stream |
SSE; event: audio frames {sessionId, seq, text, audio(base64 MP3)} |
POST /dsh-voice-api/asr |
raw little-endian f32 PCM body → {text} via SenseVoice |
POST /dsh-voice-api/cancel |
{sessionId} drops queued + in-flight synthesis (epoch bump) |
GET /dsh-voice-api/config |
ASR runtime config {asr: {...}} for the mic button |
GET /dsh-voice-api/hf/* |
cache-through HF model proxy (mirrors to cacheDir) |
GET /dsh-voice-api/* |
ping: {ok, name, enabled} |
Config (bundle patch row):
- id: voice
  name: '@haoku123/dsh-voice'
  config:
    voice: zh-CN-XiaoxiaoNeural
    cacheDir: ~/.cache/dsh-voice/models   # optional, on-disk model cache
    asr:
      model: csukuangfj/sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17
      modelHost: https://huggingface.co   # or https://hf-mirror.com
      language: auto                      # auto | zh | en | ja | ko | yue
      useItn: true                        # inverse text normalization
      autoSend: false
      mode: toggle                        # toggle | hold
      hotkey: Control                     # keyboard press-to-talk; '' disables
Model files are fetched through the proxy on first use; warm the cache once with the dsh host running:
npm run prefetch # uses http://127.0.0.1:3080 by default
Install
dsh plugin --profile web add <repo-url-or-path>
dsh --profile web
Note: needs Node ≥ 22.19 or ≥ 24 (node:zlib zstd APIs).
Tests
npm test                                # segmenter unit tests (pure, no network)
node test/host.integration.test.mjs     # llm/stream tap + real Edge TTS + SSE + /config
node test/bargein.test.mjs              # client inject face wiring (skipPlayback/cancelTurn)
node test/bargein-semantics.test.mjs    # aborted turn no-flush + cancel drops in-flight
node verify-client.mjs                  # client bundle registration/exports/slots/dynamic-import
原始 README: https://github.com/haoku123/dsh-voice/blob/main/README.md ↗
同类插件
查看全部 →
dsh-web-ui-all
DSH Web UI 插件与皮肤合集:任务看板、git 图、右侧面板、远程移动端 UI、桌宠、实时 token 统计与皮肤中心。
dsh-web-ui
DSH Web UI 插件与皮肤合集:任务看板、git 图、右侧面板、远程移动端 UI、桌宠、实时 token 统计与皮肤中心。

dsh-TUI
Claude Code 风格全屏终端 UI:像素鲸鱼顶栏、实时工作状态行、思考流式展开。

DSH-better-sidebar
侧边栏完整工作台:内置文件渲染编辑、终端、Git 与子代理,支持三方插件注册新 Tab。
working-activity
让 agent 的"工作状态行"活过来——实时工具动态与进度、俏皮文案、模型自述、上下文预警。同一套想法,适配两个平台: pi CLI 与 DeepSeek Harness(DSH) 。

deepseek-idesign
可视化设计工作室,支持网站、App 原型、海报、信息卡、报告和杂志的模板创建、元素编辑、选区级 AI 草稿衔接与导出。